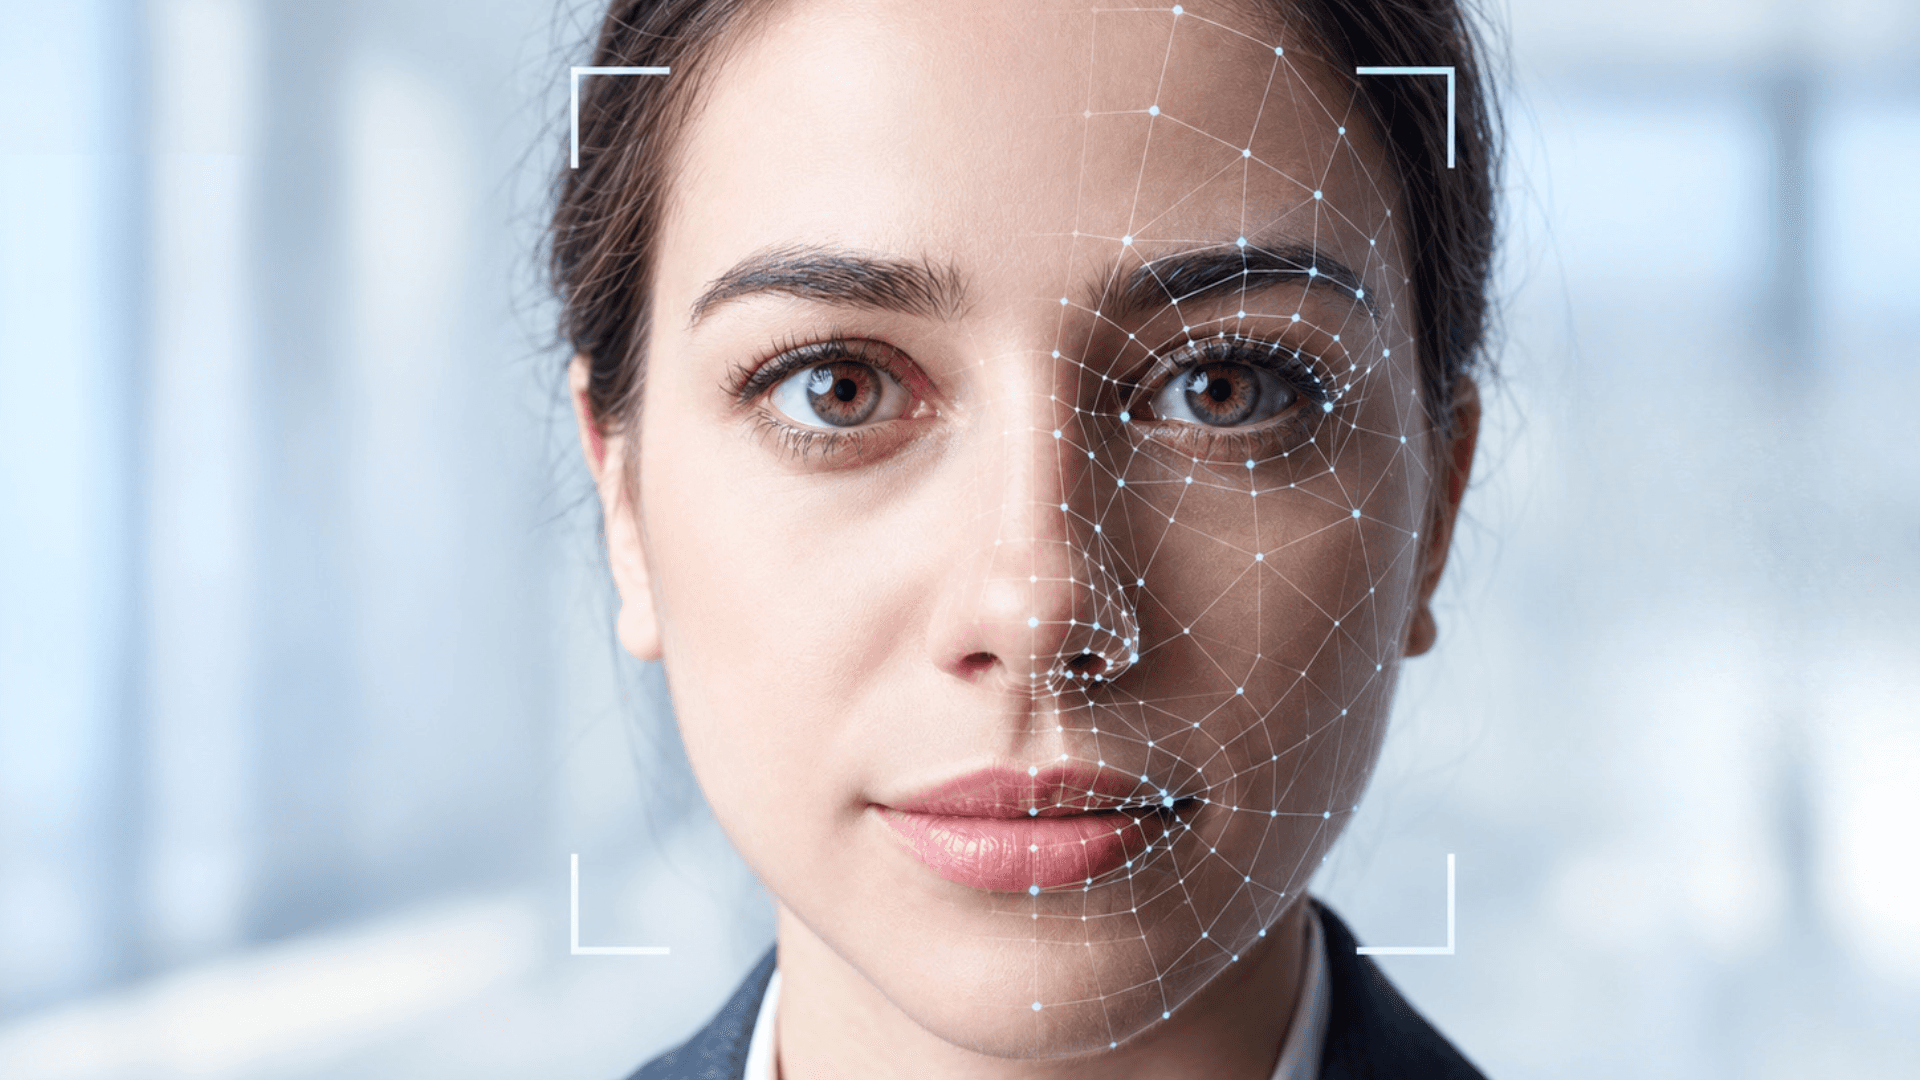
At our core is Human Insight AI, a proprietary technology that interprets human visual and behavioral signals with real-world precision.
Deployed in vehicles from the world’s leading manufacturers, in research laboratories, and wherever accurate human understanding makes a real difference. Smart Eye’s Human Insight AI brings together a set of core technologies, each interpreting a different signal of human behavior.
Head, eye & gaze tracking
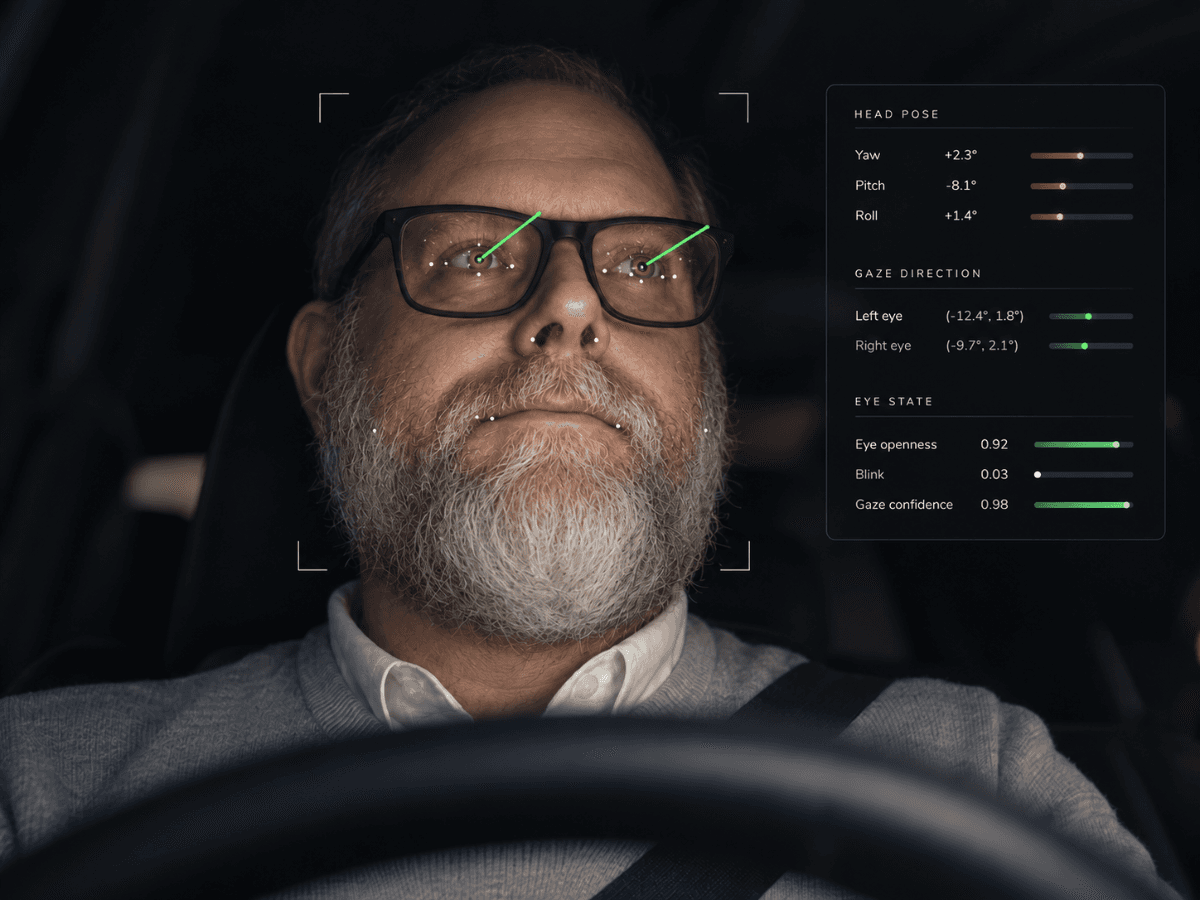
We assess alertness, attention, and focus by measuring a person’s gaze and eye movements, creating a clear picture of their awareness.
Facial expression analysis
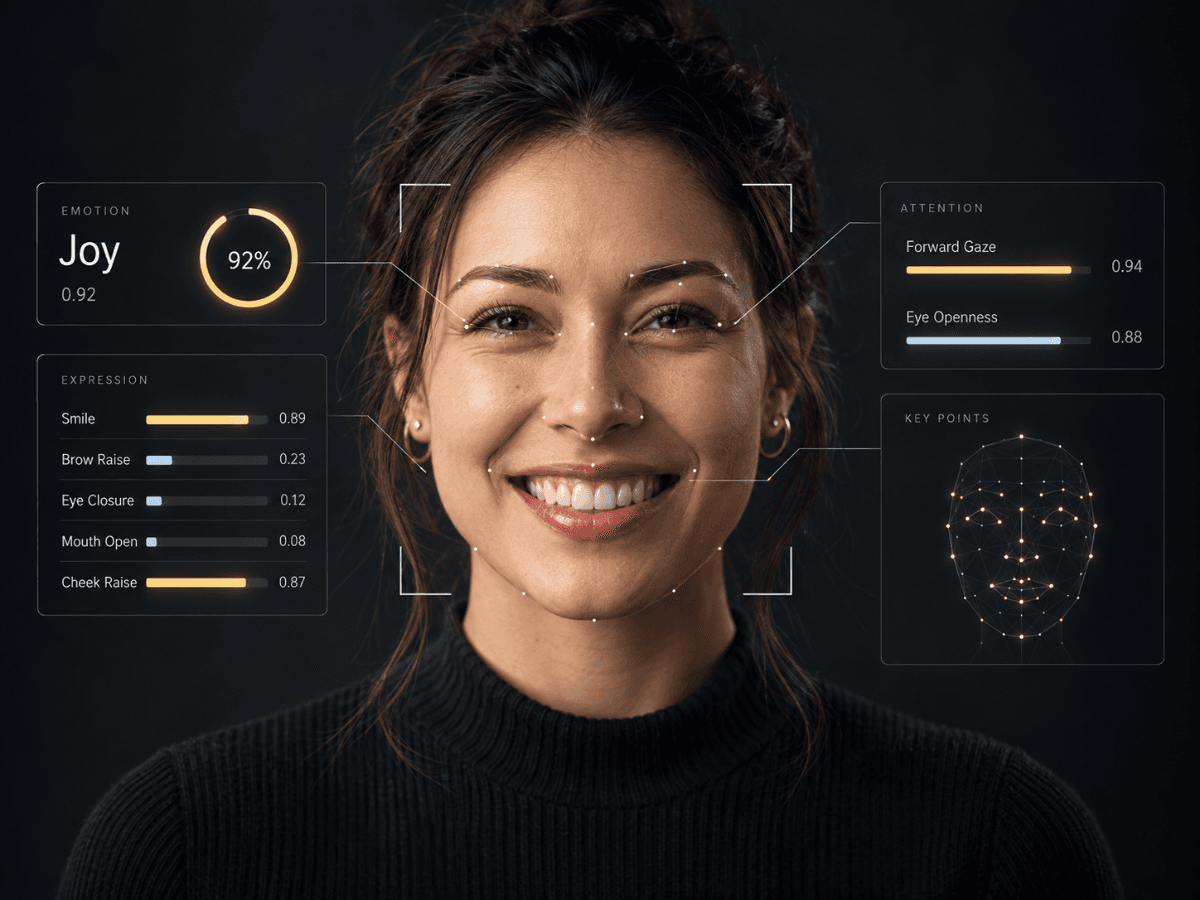
Our Affectiva-powered algorithms assess nuanced emotions and reactions through facial movements, capturing feelings like happiness, confusion, fatigue, and distraction.
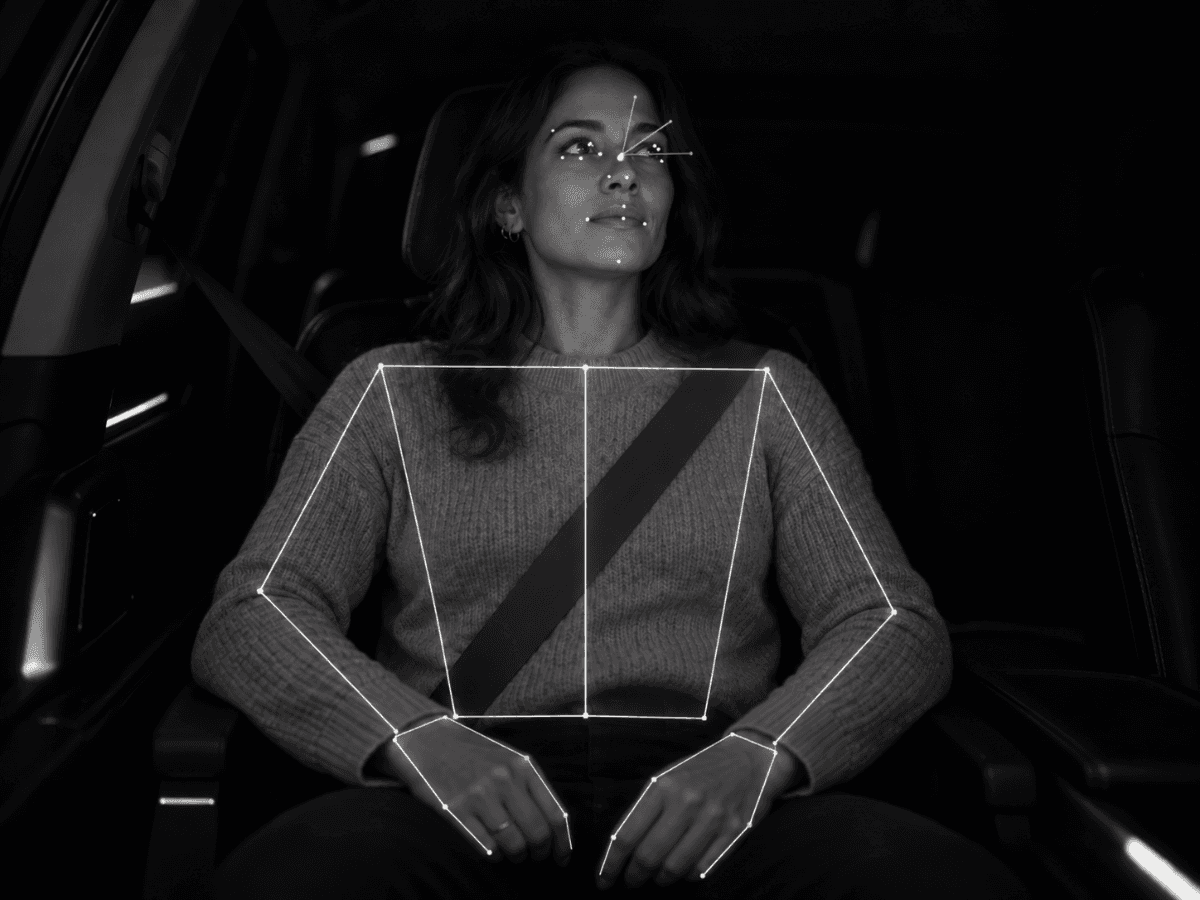
Activity & body pose tracking
Movement reveals intent. We analyze activity and body posture to enhance understanding of behavior and provide insights into occupant safety and well-being in vehicles.
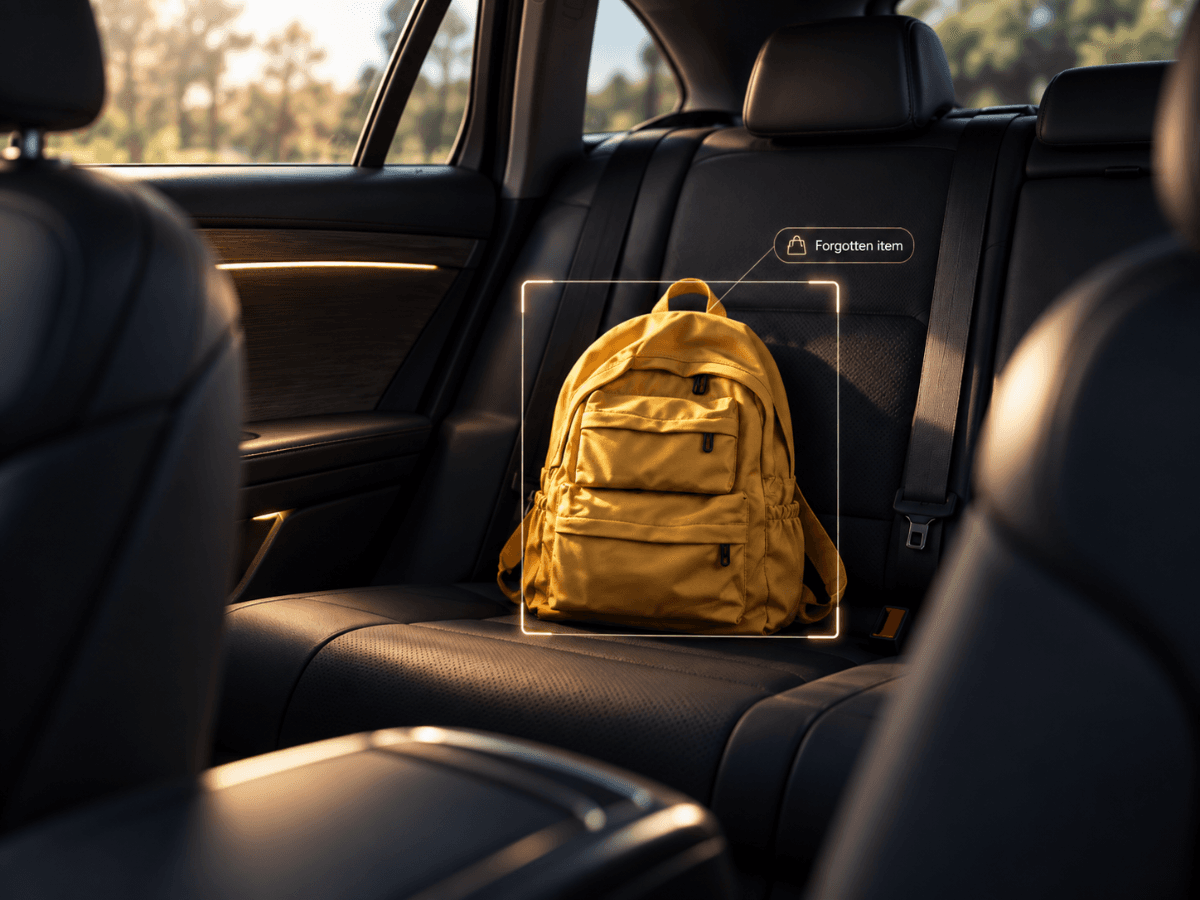
Object-detection
Our object-detection algorithms link people's actions to nearby objects, revealing the reasons behind their behavior. In vehicles, it can detect a child or pet left behind.
How we build it
Machine learning & computer vision
Our technology starts with images from cameras and optical sensors, interpreted through computer vision. Machine learning trains and validates the algorithms, with data as the teaching material. The result is a system that tracks faces and body points and analyzes behavior accurately, at scale and repeatably.
Data fusion
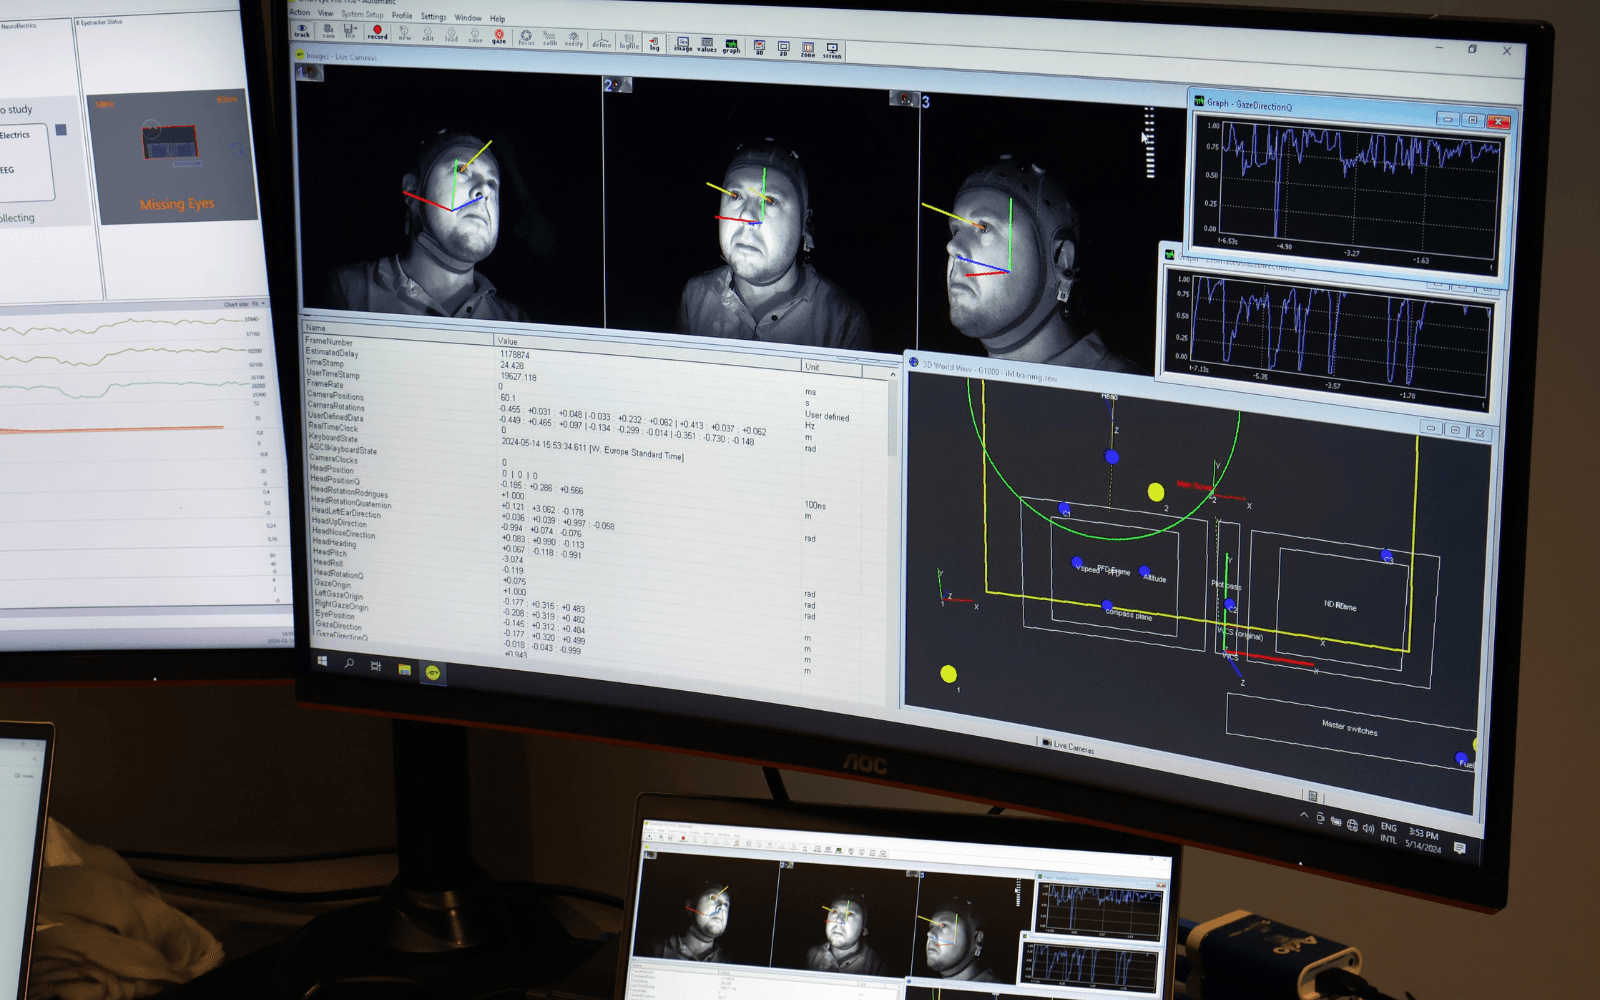
Through iMotions, we combine and synchronize data streams from multiple sensors — eye tracking, facial expressions, physiological and behavioral signals — into a single, holistic view. This multimodal approach interprets several signals together rather than relying on any one alone.
Data collection & annotation
Our algorithms learn from more than 28,000 hours of automotive driving data, Affectiva’s 17 million face videos (5.8 billion facial frames from 90 countries), and Sightic’s real-world impairment data, supplemented by synthetic data we generate ourselves. Ethical AI is a priority: our data is deliberately diverse across gender, ethnicity, and age to reduce bias.
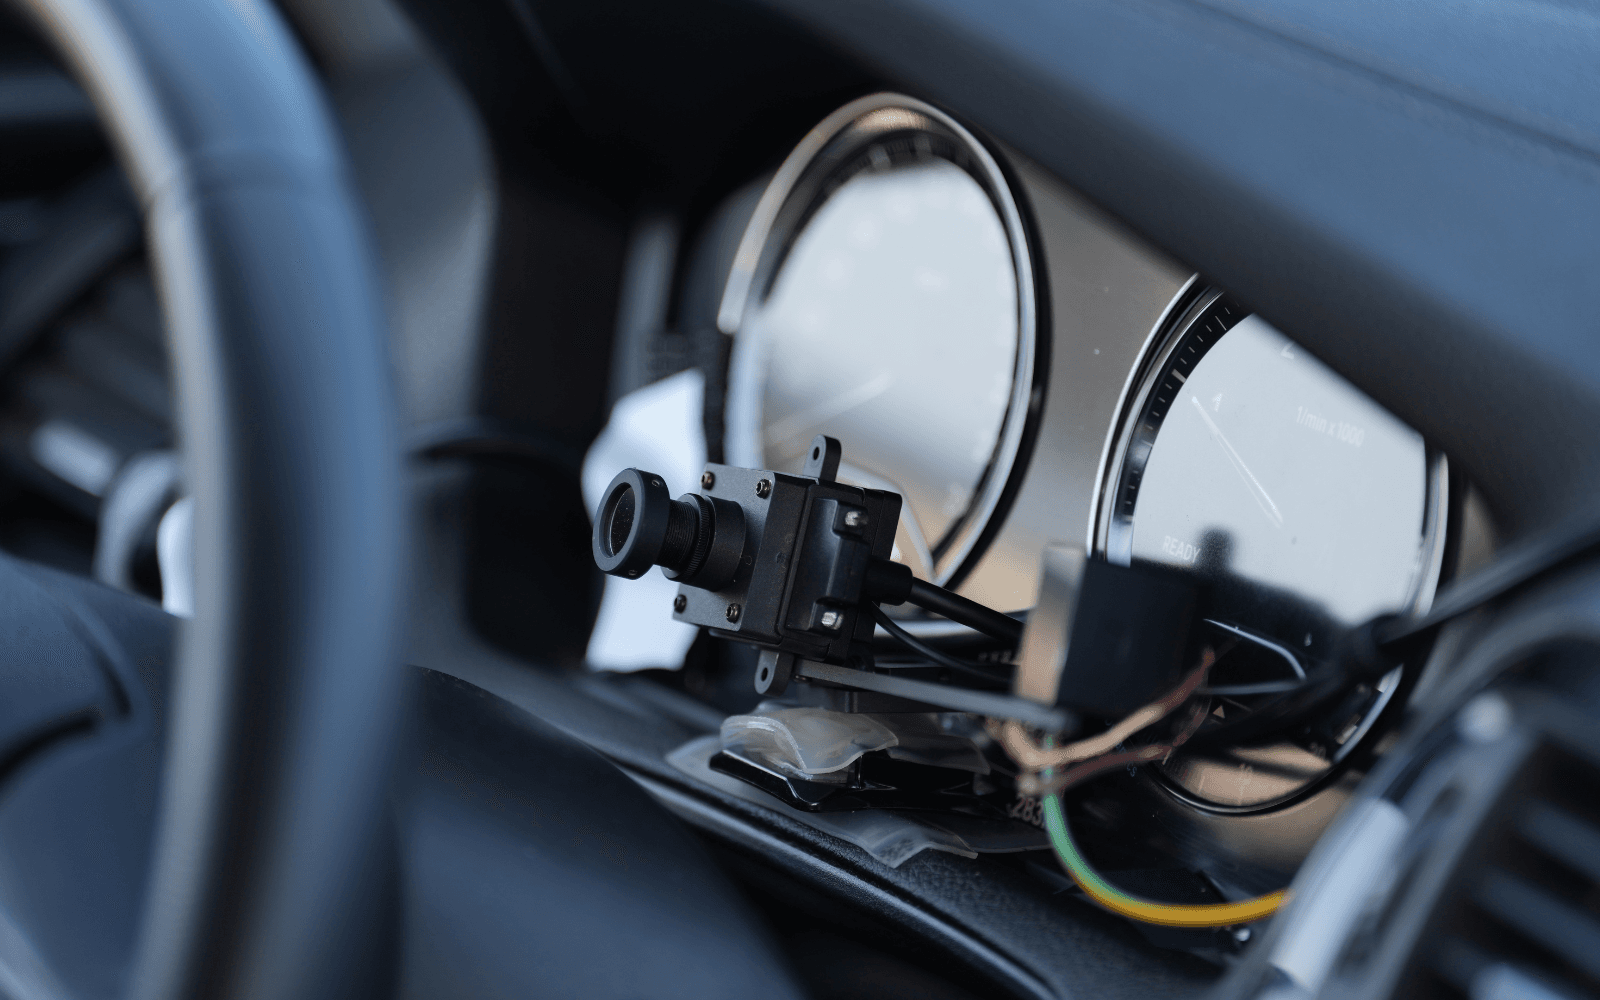
Agnostic Platform & SDK
Our software runs on-device, independent of SoC and camera, and supports multi-camera setups built to ASIL quality. Teams can start with an evaluation kit, then use the SDK to integrate on a PC or embedded platform, test in the vehicle and measure real algorithm performance.
Our patent portfolio reflects the pace of our innovation in multimodal Human Insight AI, with broad applicability across industries, use cases, sensors and platform.
103
Patents issued
64
Patents pending
Innovation
Innovation is central to Smart Eye across Automotive and Behavioral Research. Continuous investment in research and development advances our understanding of human behavior.
Our research team also advises policymakers and standards bodies, collaborates with hardware partners, and creates the datasets that power our algorithms.
Explore our Human Insight AI articles



See our technology in action and we'll help you apply Human Insight AI to your work.
Technology FAQ
Human Insight AI starts with images from cameras and optical sensors — usually one or more cameras with infrared illumination, so it works in darkness and changing light. From that input it tracks head position, each eye’s gaze, facial features and expression, body pose, and the objects a person interacts with. Multi-camera setups widen the tracked area and keep performance stable when a person moves or turns away from any single camera.
Our algorithms learn from one of the largest real-world datasets of its kind — spanning tens of thousands of hours of driving data, millions of face videos and billions of facial frames collected across more than 90 countries. Machine learning and computer vision do the work: the data is the teaching material and the algorithms are the students. We deliberately balance the data across gender, ethnicity and age to reduce bias, and generate synthetic data to cover rare, safety-critical cases that are hard to capture in the real world.
A single sensor only tells part of the story. Multimodal fusion combines several streams — gaze, facial expression, head and body pose, and object and context detection — into one synchronized interpretation of what a person is doing and how they’re responding. Reading the signals together is more reliable than any one alone: gaze shows where attention goes, expression adds emotional and cognitive state, and context connects both to the surroundings.
Yes. Our software is engineered to run on-device, integrated directly into vehicle platforms and third-party products, with no dependence on the cloud. It’s built to perform reliably across different hardware, lighting and vehicle types, which is what makes it suitable for large-scale production programs. For engineering teams, the SDK is the standardized way to evaluate, integrate and deploy it.
Our systems track each eye separately and combine multiple camera feeds to determine head position and gaze, so tracking continues even when one eye is occluded, the driver wears a mask or glasses, or the light shifts. Infrared illumination keeps the image usable in darkness and direct sun, and over time the system builds a profile of each face to hold head-pose accuracy when features are partly hidden.